
Vulnerabilities in Model Context Protocol expose risks in AI agent communication

Independent researcher Syed Anas Mohiuddin has identified critical security flaws in the Model Context Protocol (MCP), a standard used for communication between AI agents. The research reveals that attackers can exploit trust gaps within internal networks to perform prompt injection attacks. By compromising a single agent, malicious actors can propagate harmful instructions to other connected agents, leading to potential data exfiltration and unauthorized access to sensitive business information. Organizations including Google, JP Morgan Chase, and several government entities have acknowledged vulnerabilities related to these agent-to-agent interactions. The findings highlight a significant structural weakness in how AI agents currently handle inter-agent trust and guardrails. As organizations increasingly adopt autonomous agents, the research underscores the urgent need for more robust security protocols to prevent lateral movement and ensure that instructions passed between agents are verified and secure.
This is a summary. Read the full article at the original source:
Ars TechnicaRelated stories

Researchers from the Netherlands and Italy have unveiled a new attack that expands the Spectre-v2 class of vulnerabilities. Unlike the original 2018 a…

A new Linux-based backdoor, dubbed ClingSTUN, is actively targeting vulnerable Internet of Things (IoT) devices to transform them into proxy nodes. Ac…
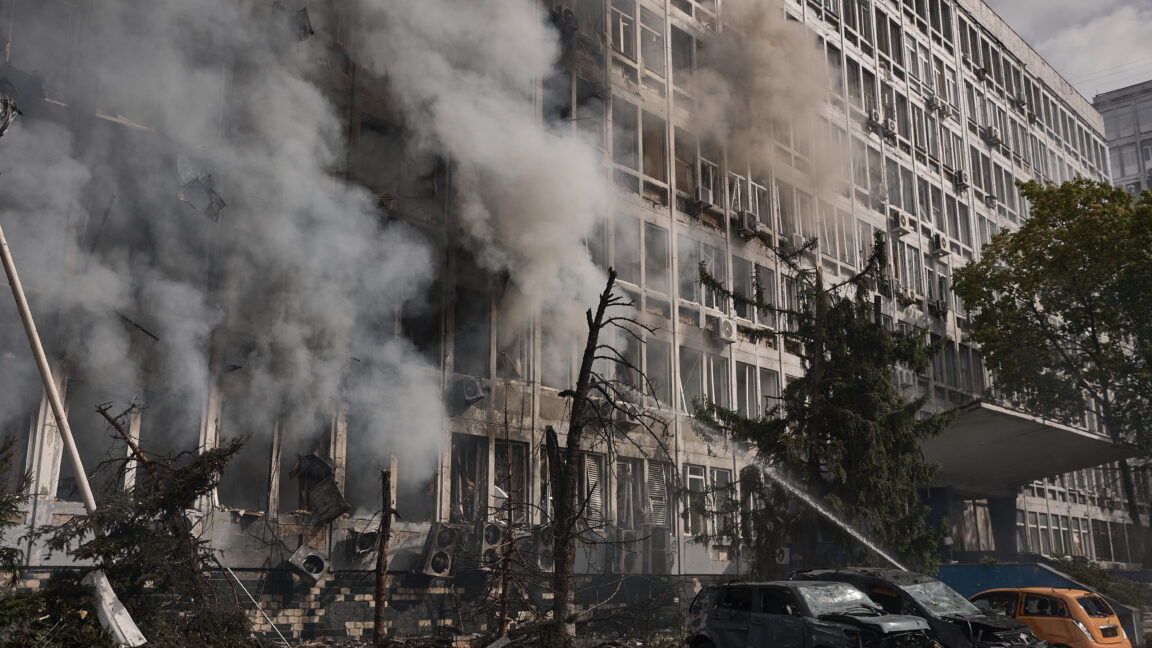
Russian drone strikes target Ukrainian data centers and telecom infrastructure
A recent escalation in Russian jet-powered drone strikes has specifically targeted data centers and telecommunications infrastructure in Kyiv, causing…