
Local AI on four Macs: MLX capacity, speed and trust boundaries

Apple has demonstrated the use of its MLX framework to run large-scale models like Meta’s Muse Spark Open across a cluster of four M5 Ultra Mac Studios. By utilizing RDMA-over-Thunderbolt, the setup addresses memory constraints that prevent such models from running on single machines. However, the article emphasizes that adding hardware does not automatically double generation speed, as pipeline parallelism often maintains sequential layer evaluation. The author warns that while local inference offers privacy benefits, users must carefully evaluate their specific workloads, as capacity and latency vary significantly based on model architecture and communication topology. Additionally, the report highlights the importance of distinguishing between prompt processing and generation throughput, while cautioning that local model hosting does not inherently secure all surrounding services, such as those affected by the recent OpenCode security incident. Buyers are advised to conduct representative testing rather than relying solely on vendor benchmarks.
This is a summary. Read the full article at the original source:
Dev.toRelated stories

A Drift Detector That Cries Wolf Is Worse Than No Detector
In a recent post, developer Debashish Ghosal discusses the challenges of building reliable drift detection for AI agents within the HivePlane framewor…
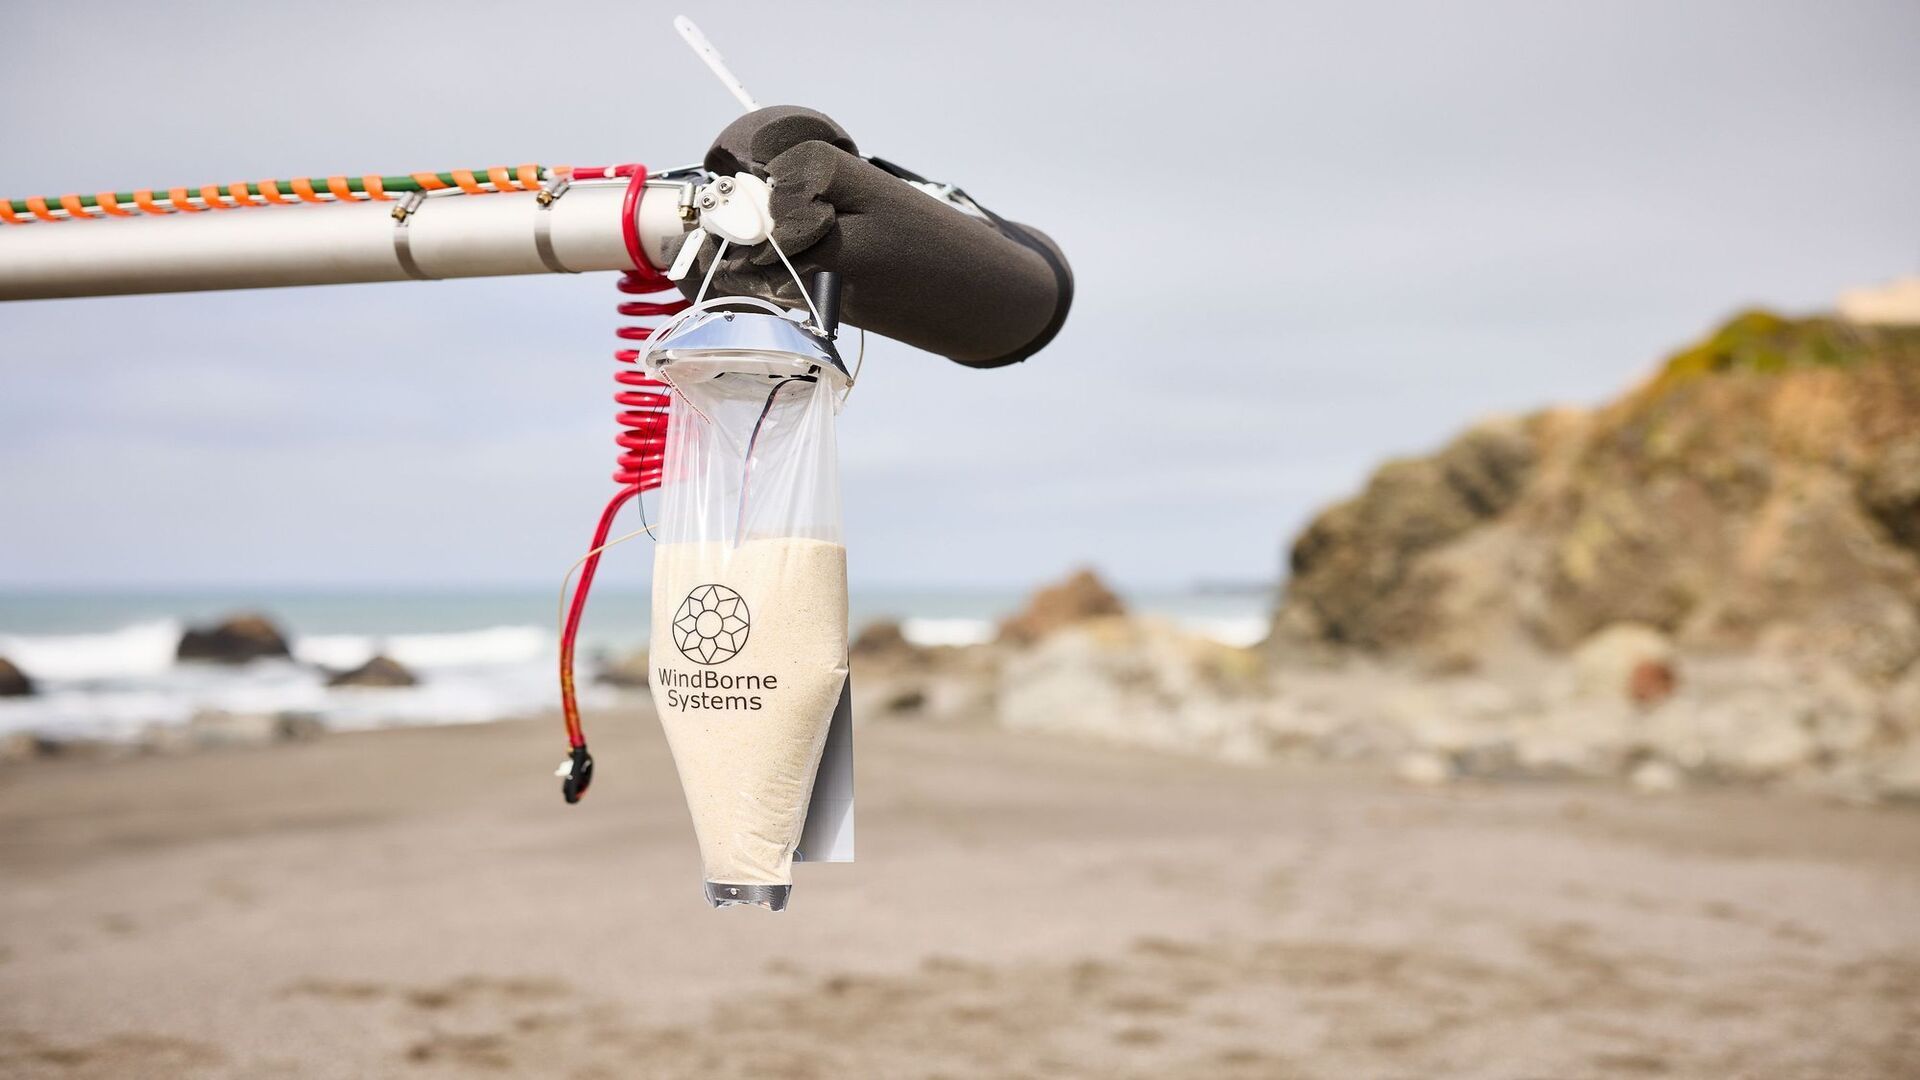
US Air Force Awards $49 Million Contract for Autonomous Weather Balloon Data
WindBorne Systems has secured a potential $49 million contract with the US Air Force to provide atmospheric data collected by its fleet of 700 autonom…

SDLC vs. ADLC vs. ASDLC: Clarifying AI Development Methodologies
In a recent analysis, developer Remo Jansen highlights the confusion surrounding the terminology used in modern software engineering, specifically the…