

In a recent experiment, developer Ken Walger tested whether Large Language Models (LLMs) are necessary for common tasks like data extraction, classification, and question answering. Using a Raspberry Pi 4 and small models like Qwen2.5:1.5b, he compared their performance against deterministic methods like regular expressions. The results were revealing: for simple extraction, a regex was faster and perfectly accurate, whereas LLMs struggled with formatting and hallucinations. For classification, small models failed to grasp complex routing decisions, often miscategorizing critical inputs. While LLMs showed promise in grounded question answering, they frequently fabricated information when answers were absent. Walger concludes that developers should prioritize the simplest possible solution—such as deterministic code—before defaulting to LLMs. He emphasizes that while context is cheap, model latency and reliability remain significant hurdles, suggesting that LLMs should only be used when their specific strengths in reasoning are truly required.
This is a summary. Read the full article at the original source:
Dev.toRelated stories

Shopify has announced a significant expansion of its agentic commerce strategy, allowing a broader range of AI agents to browse and purchase products…

New GPT-6 builds ChatGPT responses from charts, buttons, and forms. OpenAI has not disclosed how brands get featured
With the release of GPT-6 updates, ChatGPT has begun integrating interactive elements like charts, forms, and buttons into its responses. This innovat…
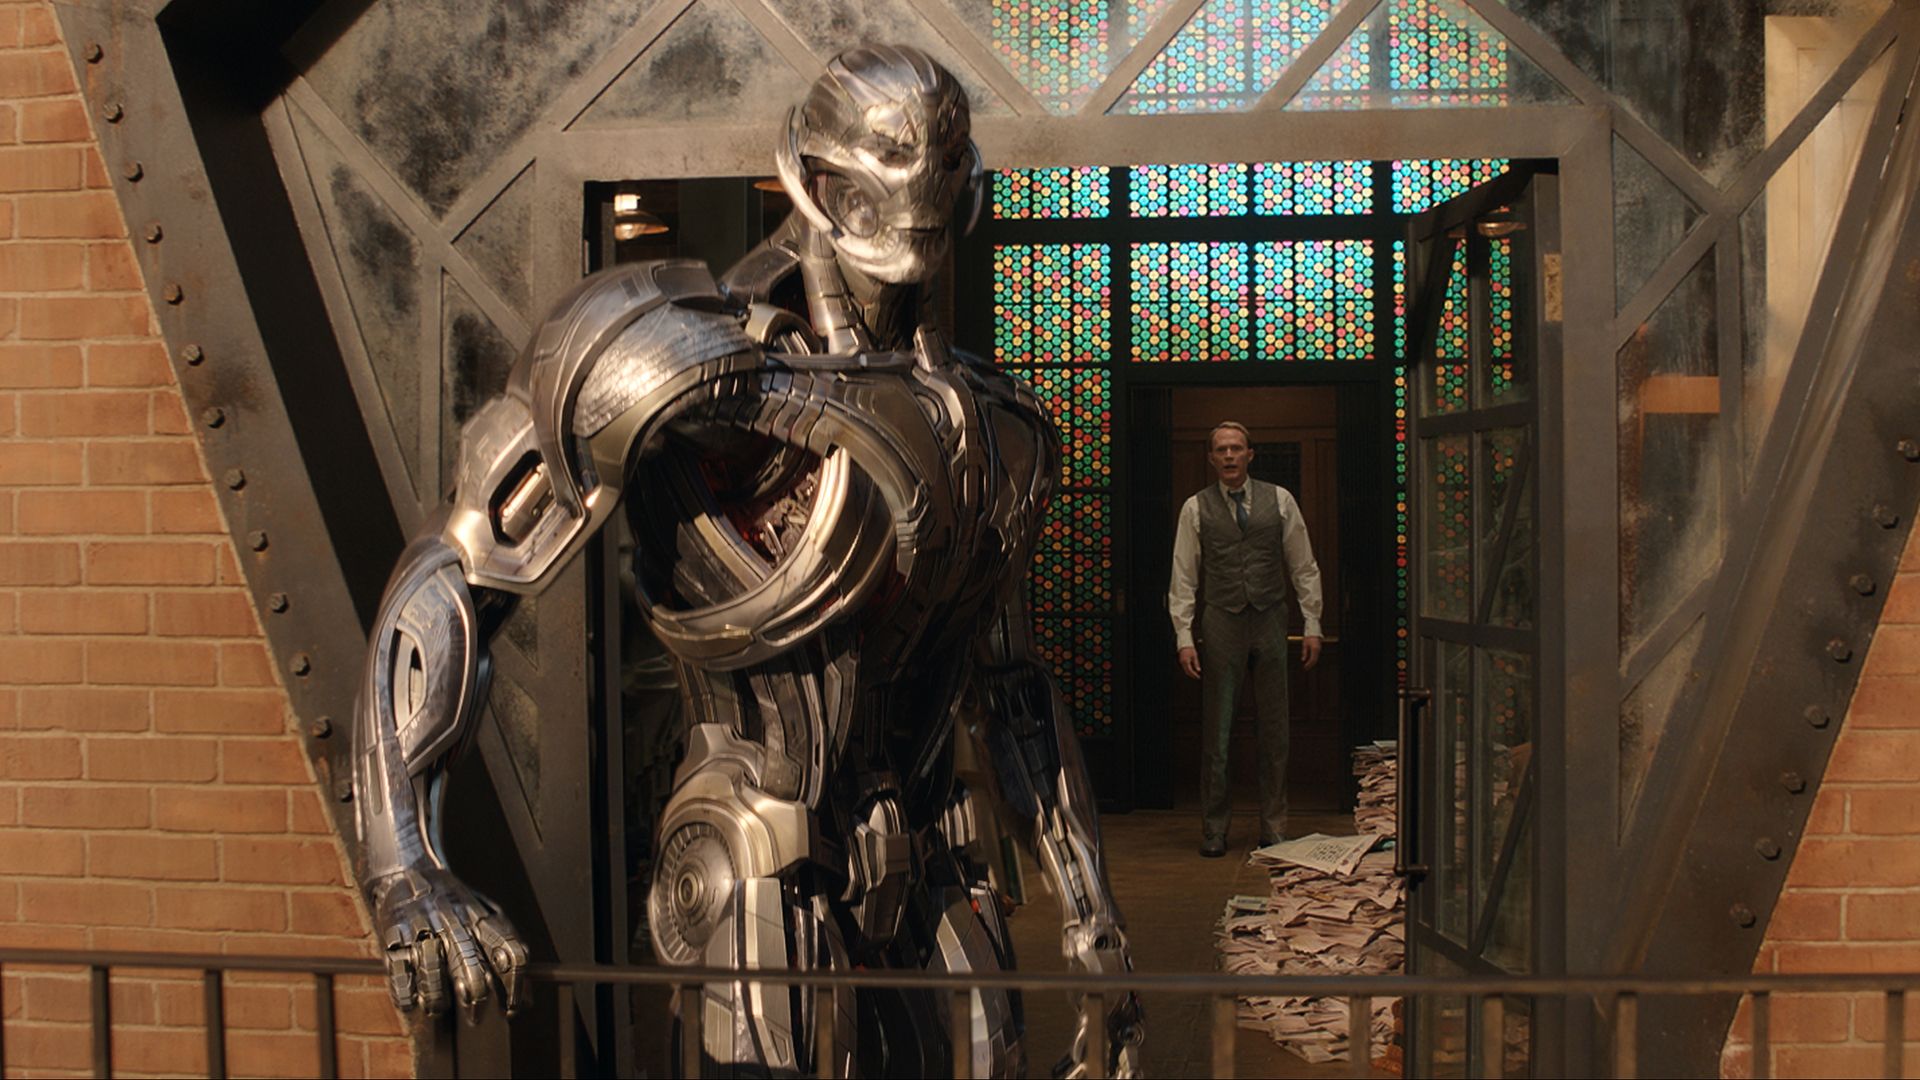
James Spader teases a more mature and dangerous Ultron in VisionQuest
Actor James Spader has provided new insights into the return of the iconic villain Ultron in the upcoming Marvel series, VisionQuest. Twelve years aft…