
SGLang Without Magic: How Core LLM Inference Settings Work

This article from Ecom Tech on Habr provides an in-depth analysis of the configuration settings for SGLang, a popular LLM inference framework. The author explains that as inference tasks scale, default settings often fail to address challenges like memory constraints, request queuing, and GPU underutilization. The article breaks down five critical configuration categories: various parallelism strategies (TP, DP, CP, PP, EP), KV-cache management (Radix Cache, HiCache), MoE computation specifics, attention backend selection, and speculative decoding. The goal is to help engineers understand the underlying mechanics of the inference pipeline, enabling them to make informed decisions when tuning parameters for specific workloads and hardware limitations. This guide is an essential resource for practitioners looking to move beyond basic setups and achieve maximum performance when deploying large language models.
This is a summary. Read the full article at the original source:
HabrRelated stories

AI is getting cheaper, but your computer is getting more expensive: How OpenAI and Anthropic started a price war
In September, the AI market saw a significant shift as OpenAI and Anthropic released new models with significantly lower usage costs than their predec…
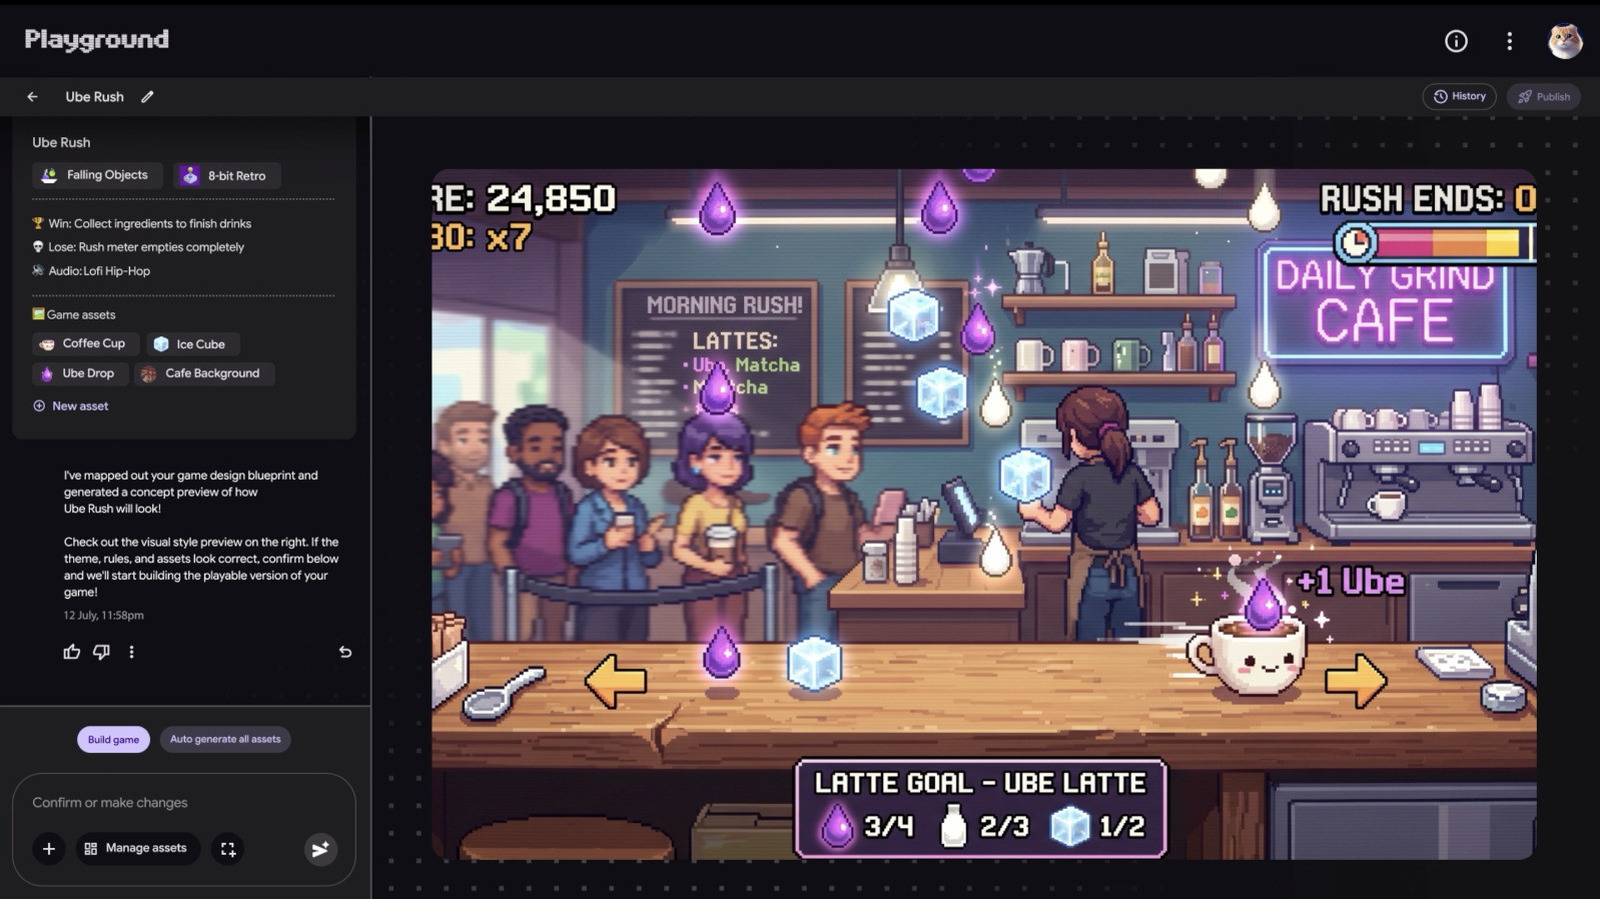
Google's experimental Playground platform uses AI to create games for you
Google has introduced an experimental platform called Playground, which leverages generative artificial intelligence to simplify the game creation pro…
Non-obvious AI capabilities: Why one should remain optimistic
The author shares their personal experience with artificial intelligence, noting that many specialists underestimate the true potential of modern neur…