
Liquid Inference: An LLM Router for Competitive Model Selection
Liquid Inference has launched as a new LLM routing platform designed to optimize how prompts are processed across various artificial intelligence providers. By functioning as a dynamic router, the service allows different AI model providers to compete for every individual prompt submitted by the user. This competitive approach aims to improve efficiency, reduce latency, and potentially lower costs by selecting the most suitable model for a specific task in real-time. As the landscape of generative AI continues to grow with numerous proprietary and open-source models, tools like Liquid Inference provide a necessary layer of abstraction for developers and businesses looking to maintain high performance without being locked into a single provider. The platform is currently featured on Product Hunt, where it is garnering attention for its potential to streamline LLM infrastructure and enhance the overall reliability of AI-driven applications.
This is a summary. Read the full article at the original source:
Product HuntRelated stories
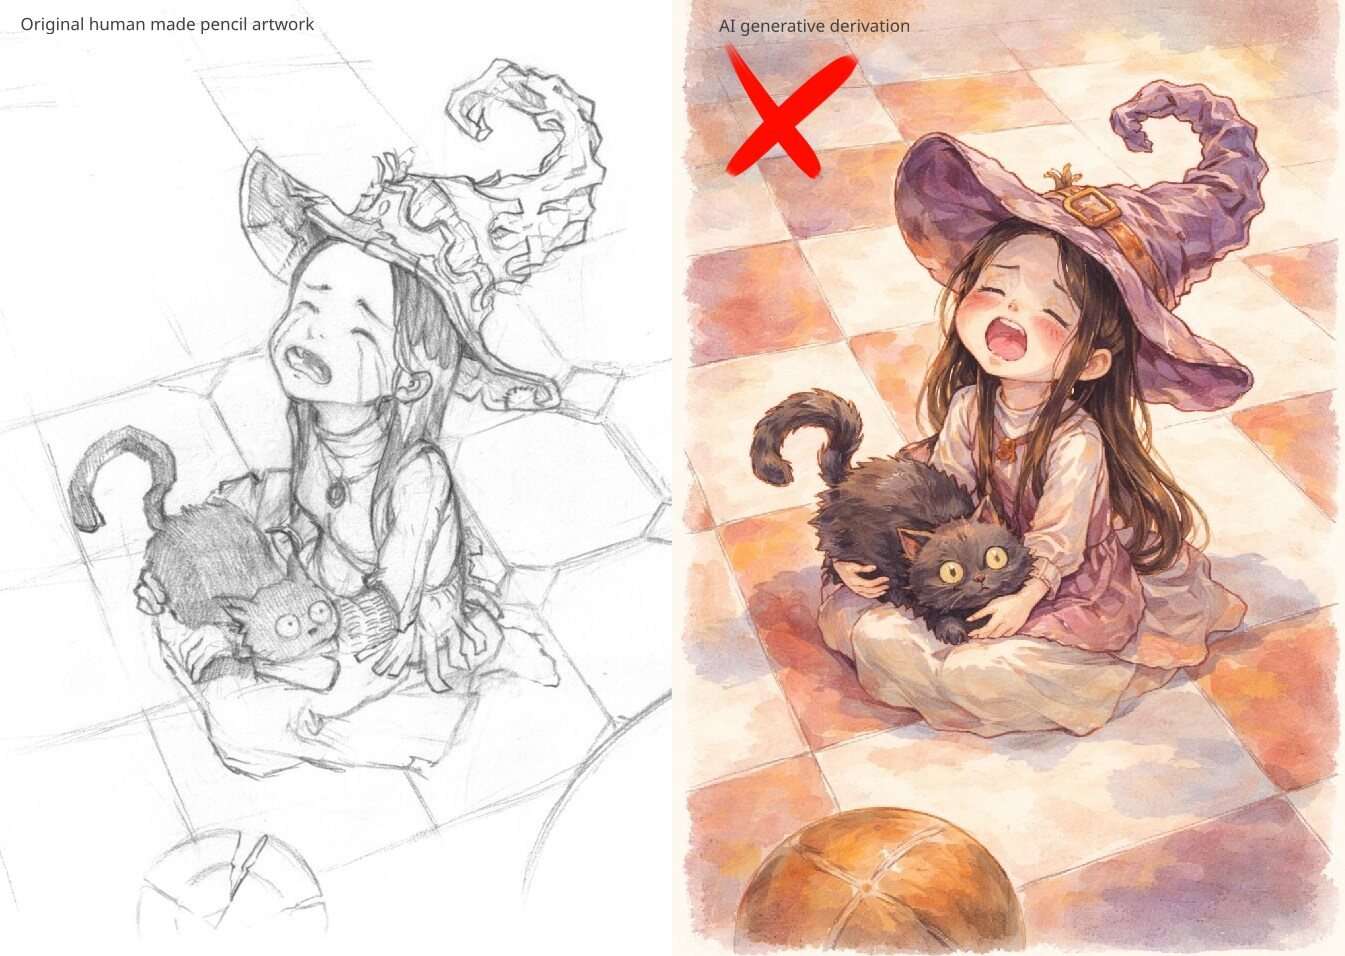
License update: AI derivation prohibited on all my art, lore, stories, and comics
Artist David Revoy has officially updated the licensing terms for his entire portfolio, including his artwork, lore, stories, and comics. The new poli…

The Artificial Intelligence Black Hole: Why Infrastructure Has Become the Industry's Main Barrier
In this article, the author analyzes the current state of the AI industry, arguing that the focus is shifting from model development to computational…

Hollywood actor Ben Affleck is gaining significant attention online for his technical expertise in artificial intelligence. Recent discussions highlig…