
How we taught LLMCOD to build a knowledge base from SPAs and open APIs, not just HTML

The developers of the LLMCOD service have introduced an update that expands the capabilities of building knowledge bases for RAG systems. The traditional method of parsing HTML code is becoming ineffective for modern SPA sites, where content is dynamically loaded via JavaScript and APIs. The LLMCOD team has implemented a mechanism that allows the system to interact with APIs and process data that does not appear in the page's source code. The article details the technical challenges the developers faced while integrating these methods and explains why vector search alone was insufficient for high-quality information extraction. The new solution allows for more efficient indexing of complex web resources, ensuring data completeness for LLM operations. The authors share their experience in overcoming the limitations of classic scraping and emphasize the importance of adapting tools to modern web application architectures.
This is a summary. Read the full article at the original source:
HabrRelated stories

A recent review of the AI agent 'Instinct' highlights the dual nature of emerging autonomous digital assistants. The author reports that the tool succ…
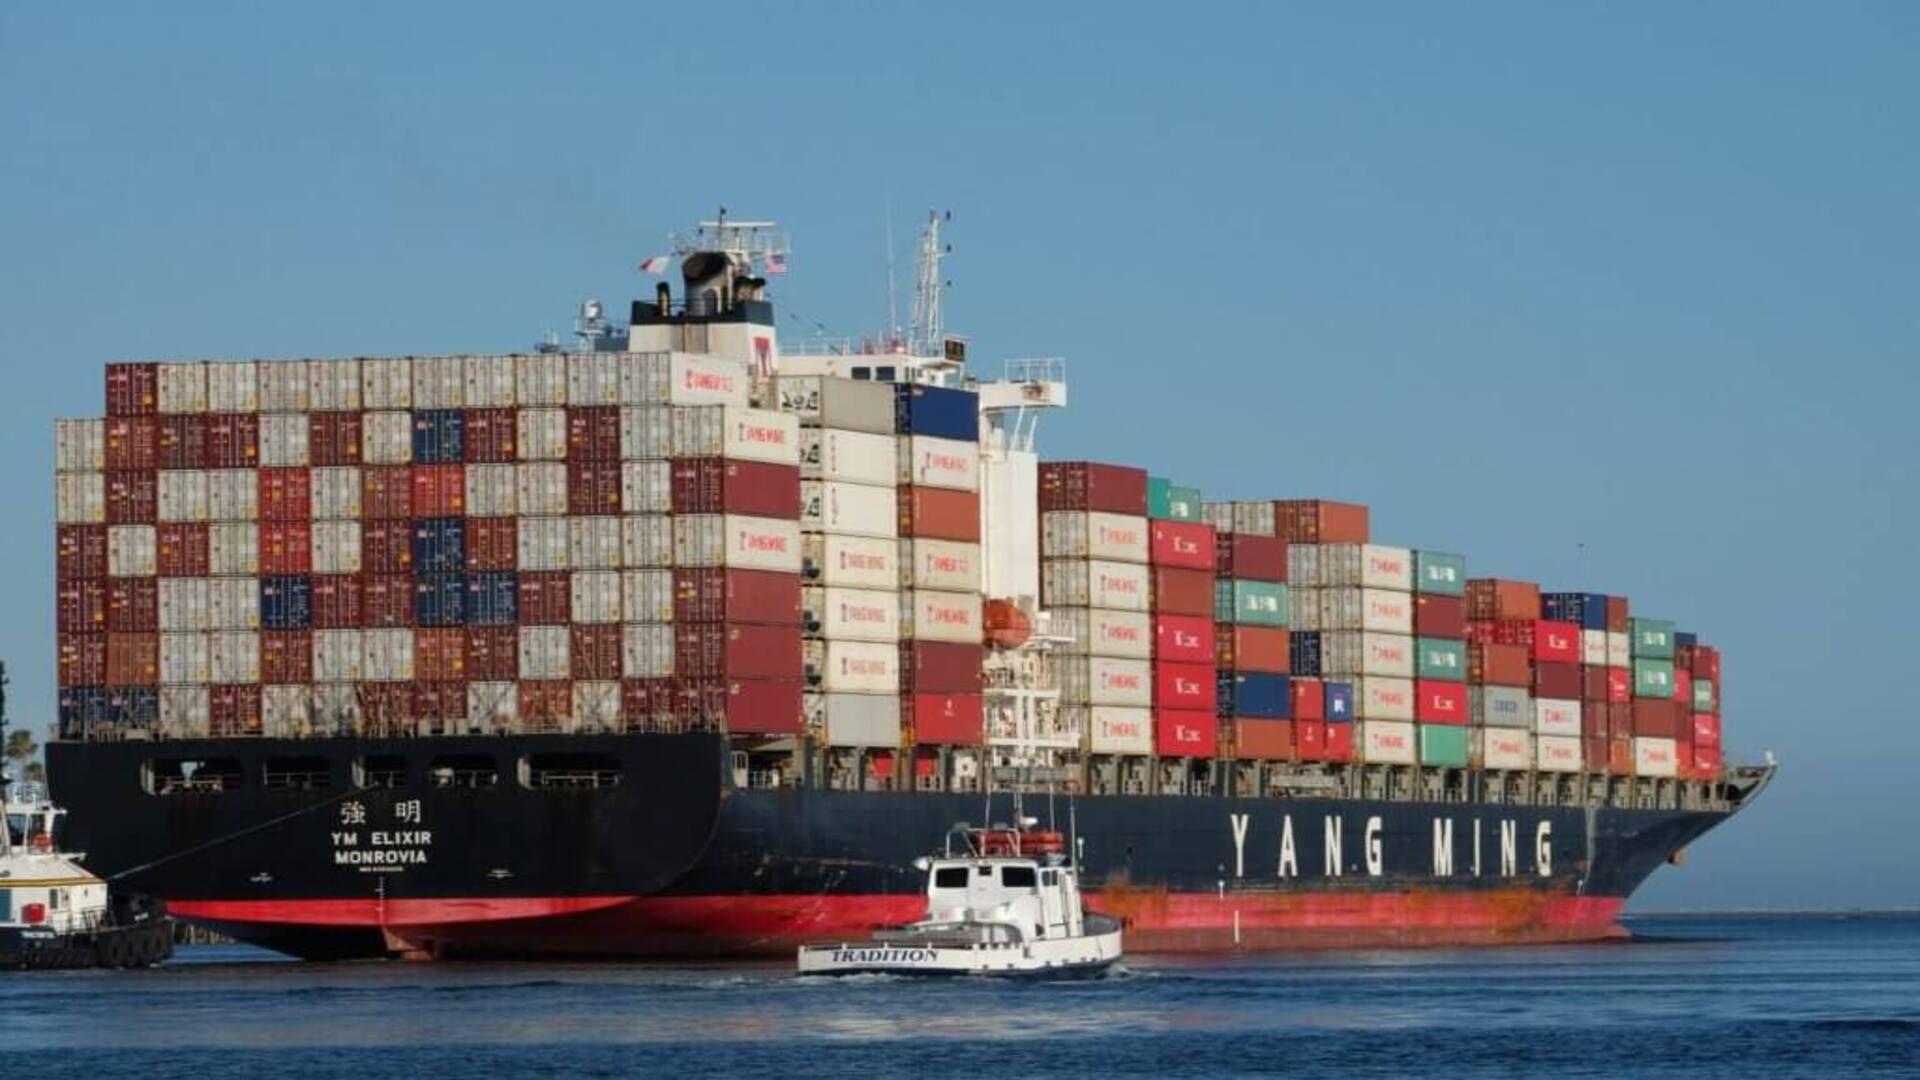
US Army nearly boarded a Chinese ship after AI-hallucinated intelligence report
A US military operation nearly escalated into a major international conflict after an AI-generated intelligence report falsely claimed a Chinese vesse…

PrismML brings its tiny LLMs to Qualcomm-powered smart glasses
PrismML has announced a strategic move to deploy its specialized tiny large language models (LLMs) onto smart glasses equipped with Qualcomm processor…