
How string indexing changed the HydraScript type system
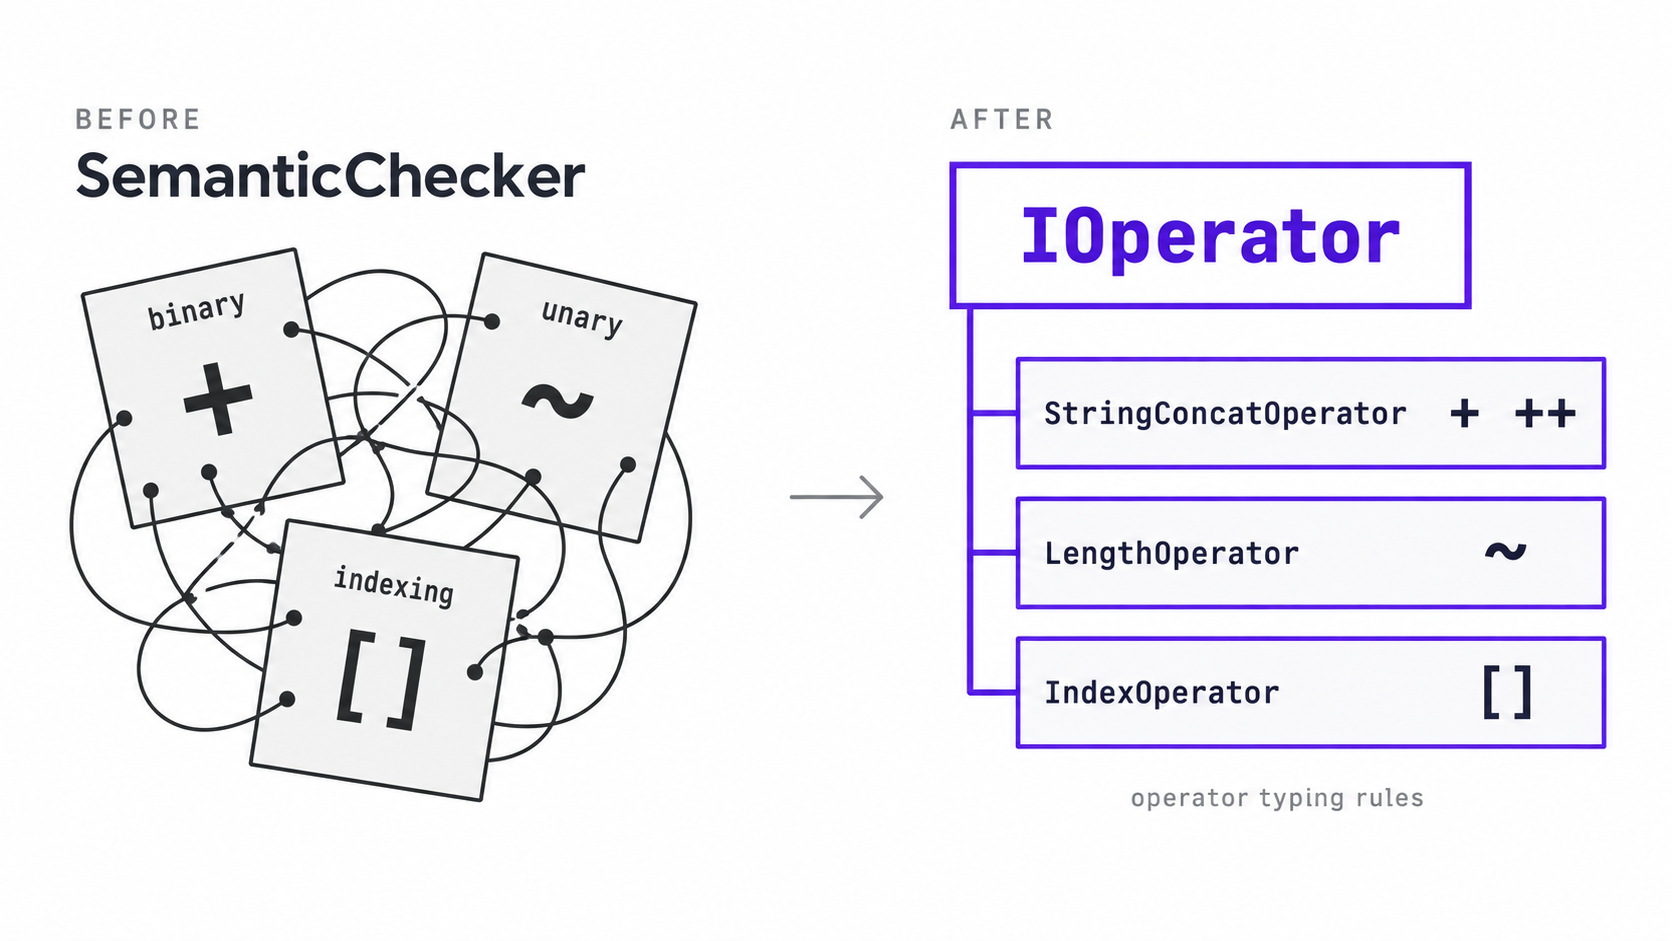
The creator of HydraScript, an interpreted programming language written in C#, discusses the process of implementing string indexing and length retrieval. Previously, these operations were exclusive to arrays, and type-handling logic was scattered throughout the semantic analyzer. To support the text[index] syntax, the developer had to refactor the analyzer's architecture to centralize type processing rules. Since HydraScript is statically typed, the main challenge was validating operations during the analysis phase rather than at runtime. This change not only added functionality but also simplified the codebase, making the type system more predictable and extensible. The article details the technical challenges faced during the integration of these features into the project's semantic analyzer.
This is a summary. Read the full article at the original source:
HabrRelated stories
DBML Diagram 1.0.1: New features for database schema management in JetBrains
Version 1.0.1 of the DBML Diagram plugin for IntelliJ IDEA has been released, aimed at database visualization and design. The key update includes full…
The article introduces the RUSI++ project, which aims to implement the Russian language into system programming with a C-like syntax. The author modif…
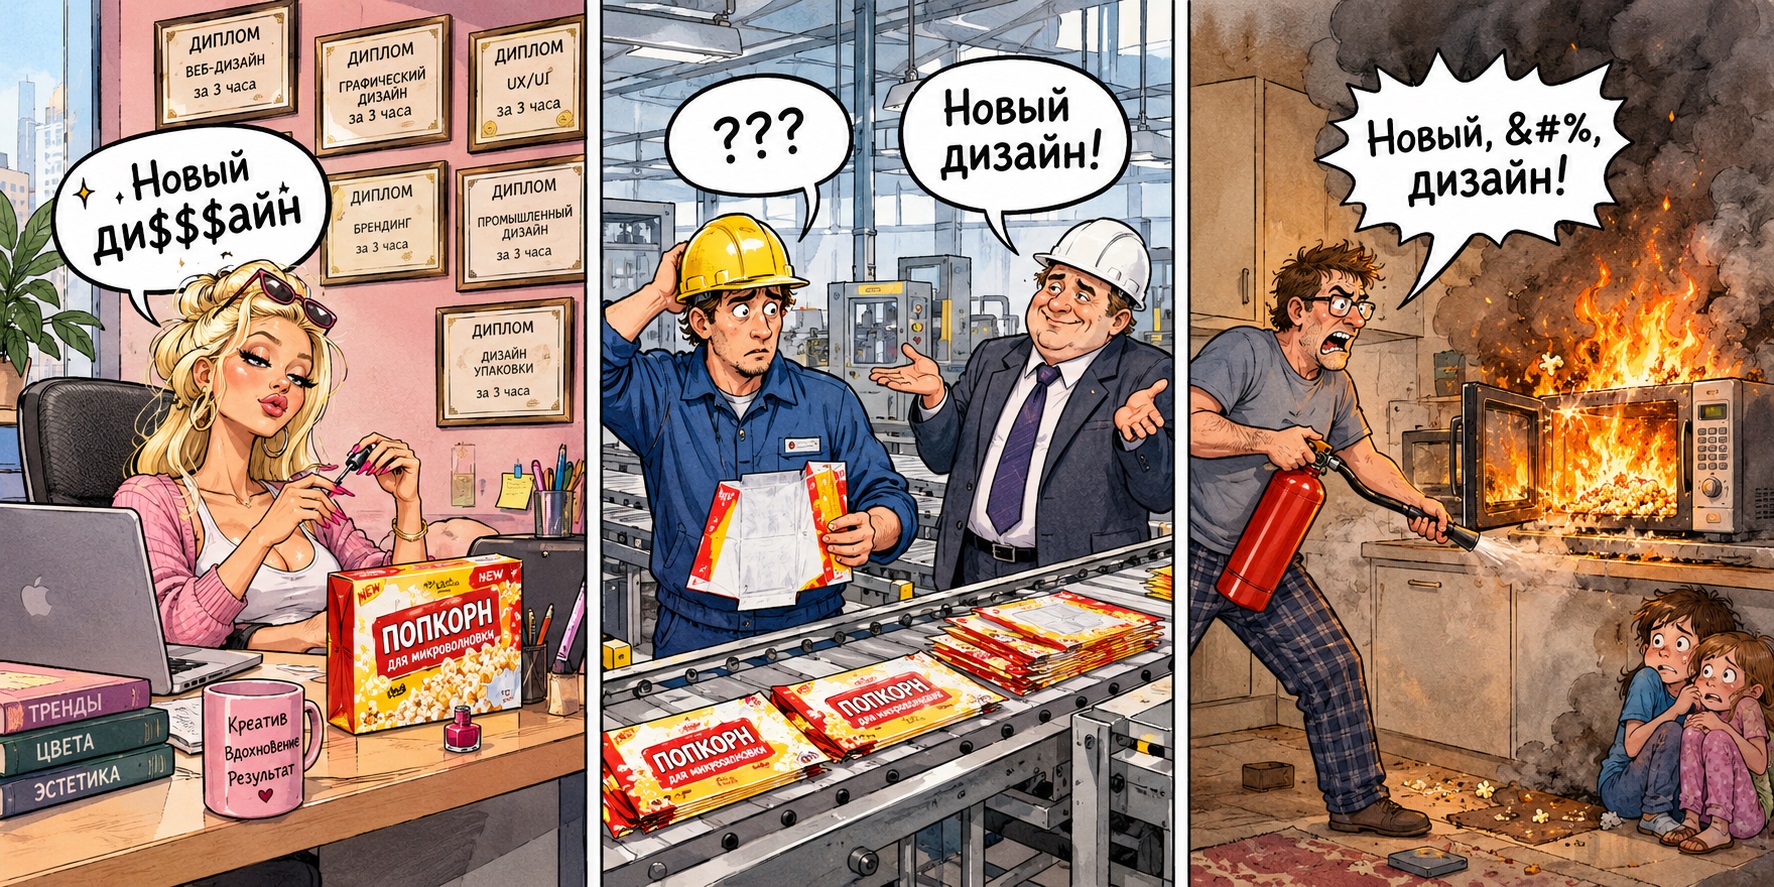
Is intelligence important in industrial design?.. or how to burn a client
This Habr article raises a critical question about the quality of industrial design and the responsibility of developers toward the end consumer. The…